The best checkpoint was not the last one
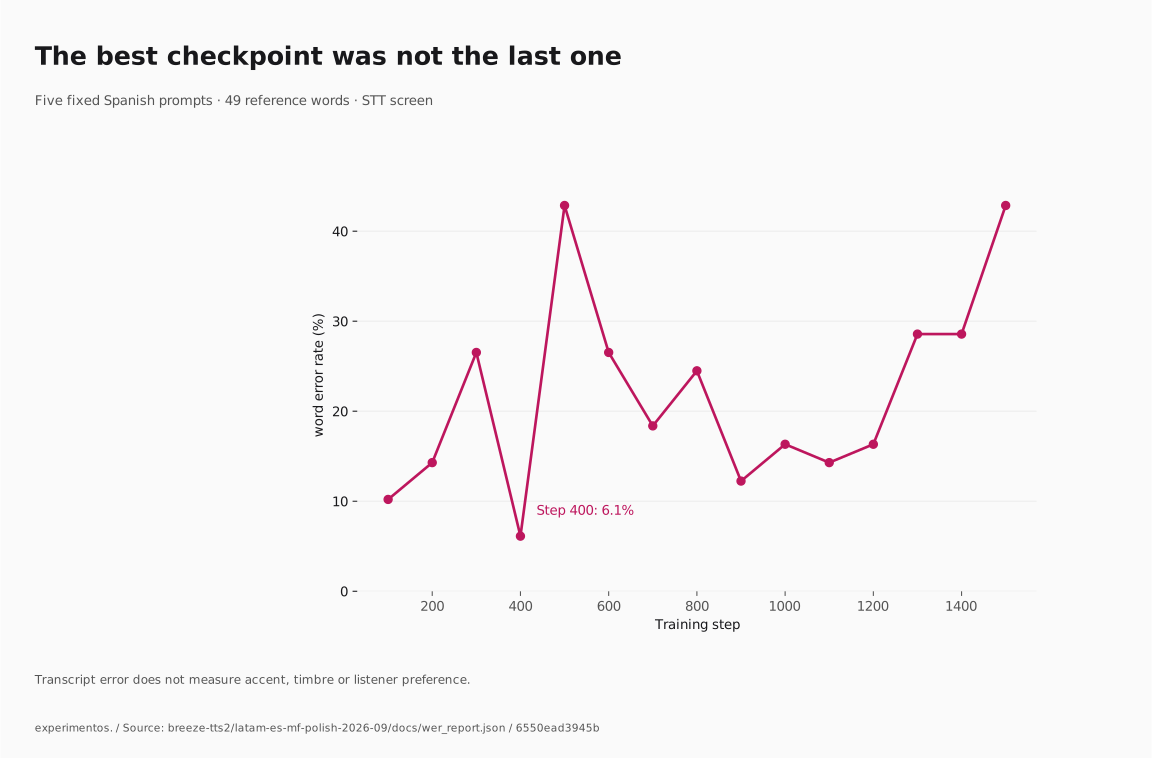
Training longer did not make every speech checkpoint better. The fixed Spanish transcription screen compared the saved steps, found an earlier best checkpoint, and retained the distinction between word accuracy and how a voice sounds.
Key finding
Polish step 400 measured 6.1% word error rate; the final step 1500 measured 42.9%.
Edited finding from the pinned experiment record. The report and figure metadata preserve the original workload and limits.
The boundary
The screen uses five fixed Spanish prompts and an STT judge. Word error rate does not measure accent, timbre or listener preference.
Data
Reviewed aggregate results with explicit units, sources and qualification limits. Different cohorts remain separate.
The best checkpoint was not the last one
Five fixed Spanish prompts · 49 reference words · STT screen
Transcript error does not measure accent, timbre or listener preference.
View data & source
| Configuration | Value |
|---|---|
| Step 100 | 10.2 |
| Step 200 | 14.3 |
| Step 300 | 26.5 |
| Step 400 | 6.1 |
| Step 500 | 42.9 |
| Step 600 | 26.5 |
| Step 700 | 18.4 |
| Step 800 | 24.5 |
| Step 900 | 12.2 |
| Step 1000 | 16.3 |
| Step 1100 | 14.3 |
| Step 1200 | 16.3 |
| Step 1300 | 28.6 |
| Step 1400 | 28.6 |
| Step 1500 | 42.9 |
Origin: structured measurements. Revision 6550ead3945b.
Write-ups
Report breeze-tts2/latam-es-mf-polish-2026-09/JOURNEY.md
The question
Training longer did not make every speech checkpoint better. The fixed Spanish transcription screen compared the saved steps, found an earlier best checkpoint, and retained the distinction between word accuracy and how a voice sounds.
From the original notebook
Journey (do not ship final step)
- Female LoRA — initial Latam-ES female-only adapter.
- M+F base run — continued to step 10250 (
latam-es-mf). - Paso0 WER screen — best base checkpoint by WER was
checkpoint-step-008000(not the final 10250). - Polish — LoRA polish started from adapter at step 8000, run
latam-es-mf-polish, 1500 polish steps oncuda:0, checkpoints every 100 steps. - Polish WER (xAI STT, es) over the 5 fixed Spanish prompts:
- Best:
checkpoint-step-000400@ 6.1% WER (3/49 edits) - Final
checkpoint-step-001500@ 42.9% WER — worse; do not ship.
- Best:
- Release choice — promote polish-400 only; other polish checkpoints deleted on disk after selection.
Release artifacts here
| Path | What |
|---|---|
samples/sample_01.wav … sample_05.wav |
Spanish samples from polish-400 |
samples/prompts.txt |
Matching reference prompts |
docs/wer_report.md / wer_report.json |
Full WER table 100→1500 |
docs/polish-run-config.json |
Polish train config |
docs/latest.json |
Points at promoted step 400 |
Polish params (summary)
See docs/polish-run-config.json for full config. High level:
- Base adapter init:
WORKSTATION/checkpoint-step-008000 - Polish run root:
WORKSTATION/latam-es-mf-polish - Device:
cuda:0(power-capped card; intentional for this polish) - Steps: 1500; save every 100
- Promoted checkpoint on server:
WORKSTATION/checkpoint-step-000400
WER ranking (avg over 5 prompts)
| step | avg WER |
|---|---|
| 400 | 6.1% |
| 100 | 10.2% |
| 900 | 12.2% |
| 200 / 1100 | 14.3% |
| 1000 / 1200 | 16.3% |
| 700 | 18.4% |
| 800 | 24.5% |
| 300 / 600 | 26.5% |
| 1300 / 1400 | 28.6% |
| 500 / 1500 | 42.9% |
STT judge: local xAI audio shim → grok-transcribe, language es.
Explicit non-goals
- Do not ship polish-1500 / TRAIN_DONE final solely because training completed.
- Prefer polish-400 (or re-listen top-3: 400, 100, 900) for release.
Deployment (2026-09-11)
Polish-400 merged + NF4 on the mfwin RTX 3060 (WSL2), served via
OpenAI-compatible POST /v1/audio/speech, set as Hermes default TTS
(breeze_latam) on .51/.54/.55/mac with boot autostart. Full report:
docs/nf4-deploy.md. Winner 10-prompt wavs under
nf4/; reproducible deploy kit under deploy/.
Keep exploring
- README.md — latam-es-mf-polish-2026-09
- nf4-deploy.md — docs
- nf4-rehost-op54-lazy.md — docs
- wer report.md — docs
Original experiment record. Workstation paths have been generalized. Detailed measurements below retain their original workload and validation boundaries.
Supporting notebooks
More in Speech & codecs
MOSS on a 3090: Q2 failed, AWQ4 stayed closer
Every profile began with the pinned BF16 generator. The comparison reused fixed reference codes and an FP32 decoder for the main quality measurements, keeping codec changes separate from generator quantization.
AWQ4 stayed close to the BF16 reference on WavLM and character errors; the sensitivity Q2 candidate was rejected.
Drama3: BF16 decoded the same codes about three times faster
The experiment replayed saved Spanish and English codes representing 21.5481 and 15.8824 seconds of audio. It compared FP32, BF16, mixed BF16 and two INT8 decoder variants on one RTX 3090.
BF16 reduced median decoder time from 390.07 to 129.54 ms in Spanish and from 292.42 to 96.88 ms in English.
Keeping FP32 and moving Supertonic to Triton
Rather than reduce the CPU graph precision again, this follow-up used NVIDIA Triton’s ONNX backend with CUDA execution and the unchanged FP32 graphs. The paired comparison retained both speed and acoustic checks.
The paired GPU test cut median first-audio time to about 0.35 seconds while preserving the measured ASR results.